PhD in Computer Science and Technology 2022.9–2028.6 (expected)
School of Computer Science, Beijing Institute of Technology
PhD candidate
Beijing Institute of Technology
Advised by Kan Li
Large language model reasoning, reinforcement learning, and evaluation, with a focus on efficient and reliable language models.
PhD in Computer Science and Technology 2022.9–2028.6 (expected)
School of Computer Science, Beijing Institute of Technology
Bachelor’s Degree 2018–2022
School of Teli Xu, Beijing Institute of Technology
Research Intern · Alibaba Qwen
2026.9–PresentResearch Intern · Xiaohongshu
2023.4–2026.8* Equal contribution
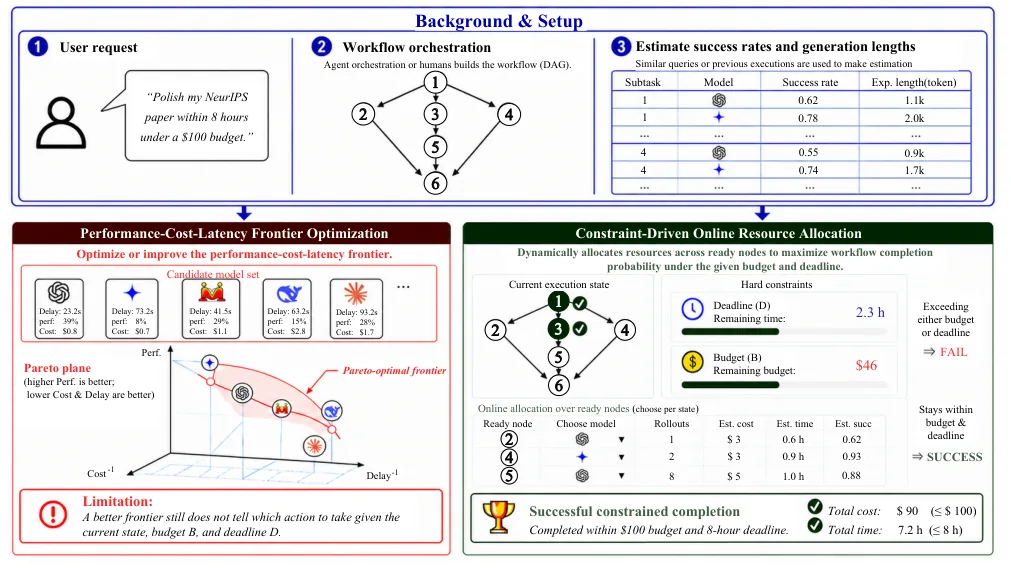
On Time, Within Budget: Constraint-Driven Online Resource Allocation for Agentic Workflows
NeurIPS 2026
Plans model choices and parallel samples across dependent agent subtasks to maximize successful workflow completion under explicit budget and deadline constraints.
@inproceedings{mcpp2026,
  title = {On Time, Within Budget: Constraint-Driven Online Resource Allocation for Agentic Workflows},
  author = {Wang, Xinglin and Liu, Zishen and Feng, Shaoxiong and Yuan, Peiwen and Li, Yiwei and Shi, Jiayi and Zhang, Yueqi and Tan, Chuyi and Zhang, Ji and Pan, Boyuan and Hu, Yao and Li, Kan},
  year = {2026},
  url = {https://arxiv.org/abs/2605.06110},
  booktitle = {NeurIPS 2026},
  note = {Accepted to NeurIPS 2026}
}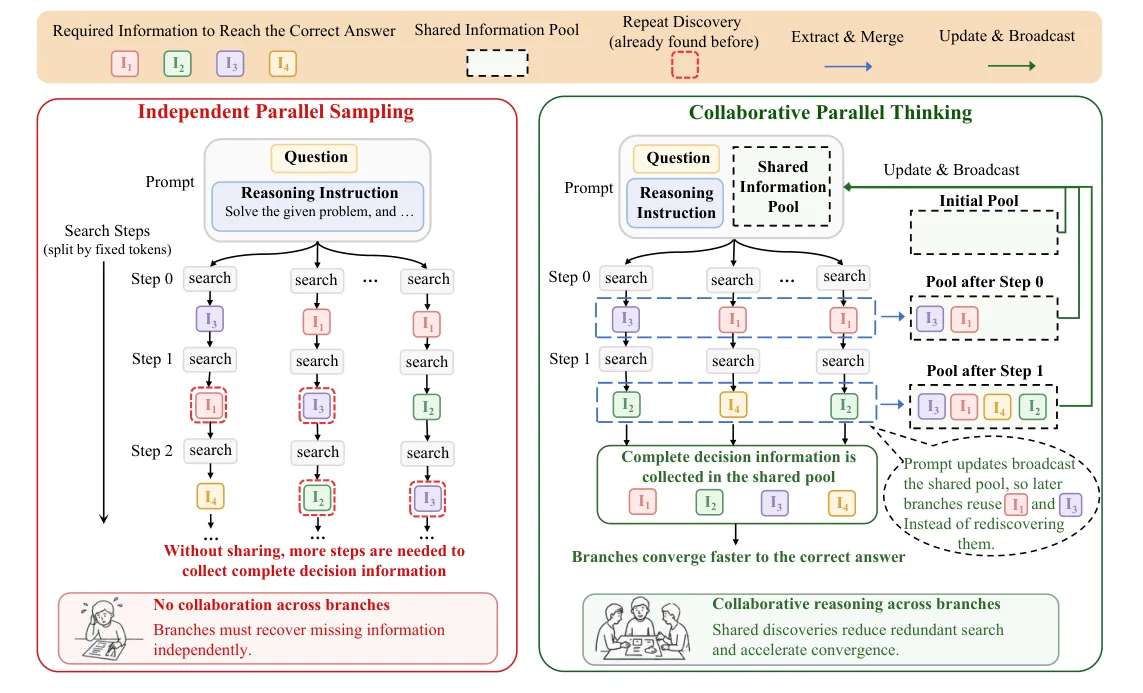
Share More, Search Less: Collaborative Parallel Thinking for Efficient Test-Time Scaling
EMNLP 2026 Oral
Lets parallel reasoning branches share compact intermediate discoveries during search, reducing repeated exploration and improving the accuracy–latency trade-off.
@inproceedings{cpt2026,
  title = {Share More, Search Less: Collaborative Parallel Thinking for Efficient Test-Time Scaling},
  author = {Wang, Xinglin and Lin, Hao and Feng, Shaoxiong and Yuan, Peiwen and Li, Yiwei and Shi, Jiayi and Zhang, Yueqi and Tan, Chuyi and Zhang, Ji and Pan, Boyuan and Hu, Yao and Li, Kan},
  year = {2026},
  url = {https://arxiv.org/abs/2605.27030},
  booktitle = {EMNLP 2026},
  note = {Accepted to EMNLP 2026 Oral}
}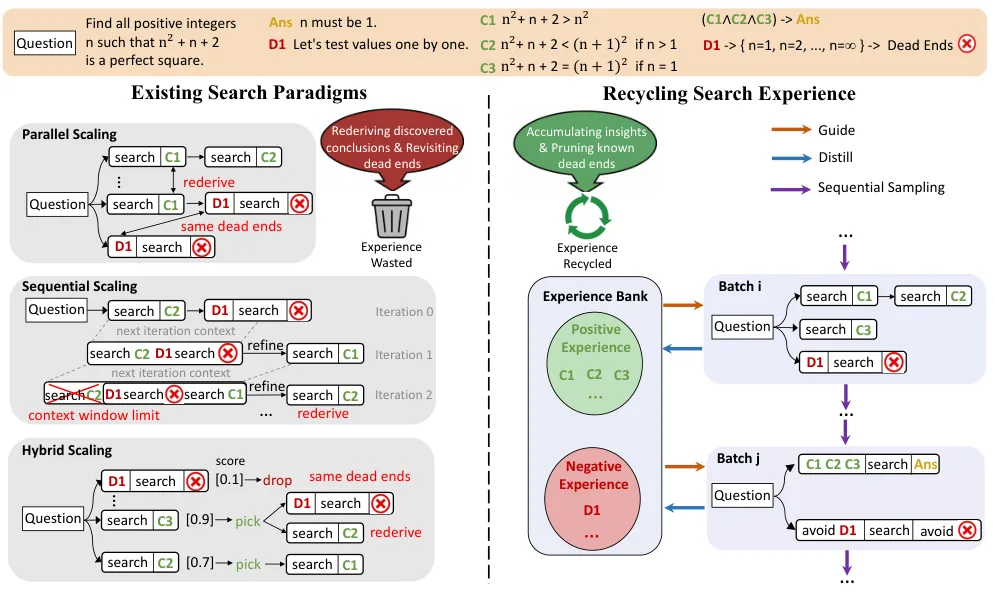
Do Not Waste Your Rollouts: Recycling Search Experience for Efficient Test-Time Scaling
Under Review
Turns successful intermediate conclusions and failed reasoning patterns into a shared experience bank, allowing later rollouts to reuse discoveries and avoid repeated dead ends.
@misc{rse2026,
  title = {Do Not Waste Your Rollouts: Recycling Search Experience for Efficient Test-Time Scaling},
  author = {Wang, Xinglin and Shi, Jiayi and Feng, Shaoxiong and Yuan, Peiwen and Li, Yiwei and Zhang, Yueqi and Tan, Chuyi and Zhang, Ji and Pan, Boyuan and Hu, Yao and Li, Kan},
  year = {2026},
  url = {https://arxiv.org/abs/2601.21684},
  eprint = {2601.21684},
  archivePrefix = {arXiv}
}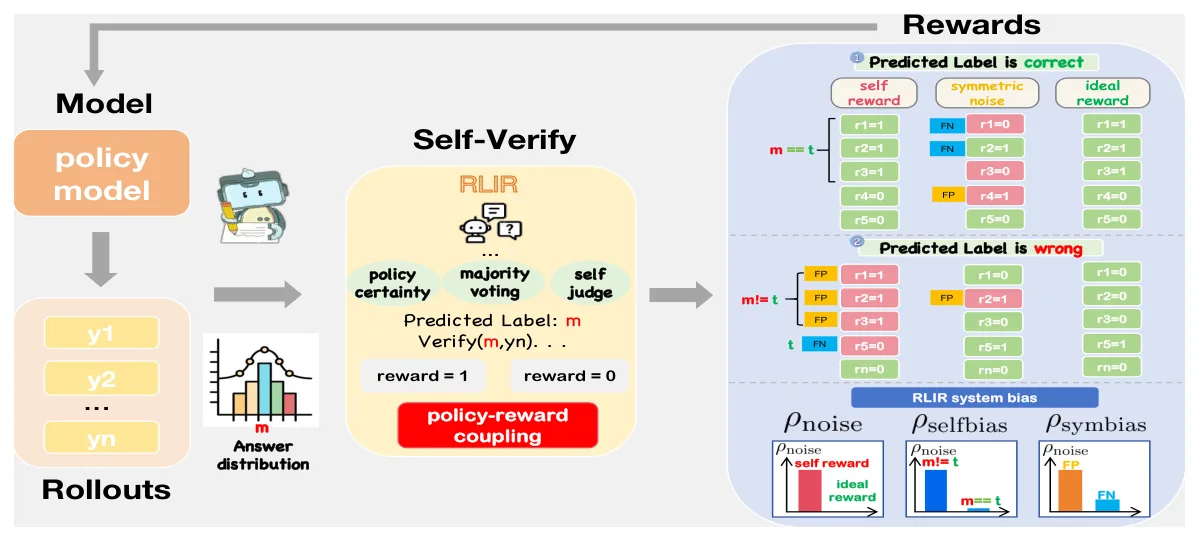
Breaking the Self-Confirming Loop: Diagnosing and Mitigating Systemic Reward Bias in Self-Rewarding RL
ICML 2026
Diagnoses feedback loops that over-reward confident mistakes in self-rewarding training and combines diverse reward models to reduce this bias.
@misc{rler2025,
  title = {Breaking the Self-Confirming Loop: Diagnosing and Mitigating Systemic Reward Bias in Self-Rewarding RL},
  author = {Tan, Chuyi and Yuan, Peiwen and Wang, Xinglin and Li, Yiwei and Feng, Shaoxiong and Zhang, Yueqi and Shi, Jiayi and Zhang, Ji and Pan, Boyuan and Hu, Yao and Li, Kan},
  year = {2025},
  url = {https://arxiv.org/abs/2510.08977},
  eprint = {2510.08977},
  archivePrefix = {arXiv},
  note = {Accepted to ICML 2026}
}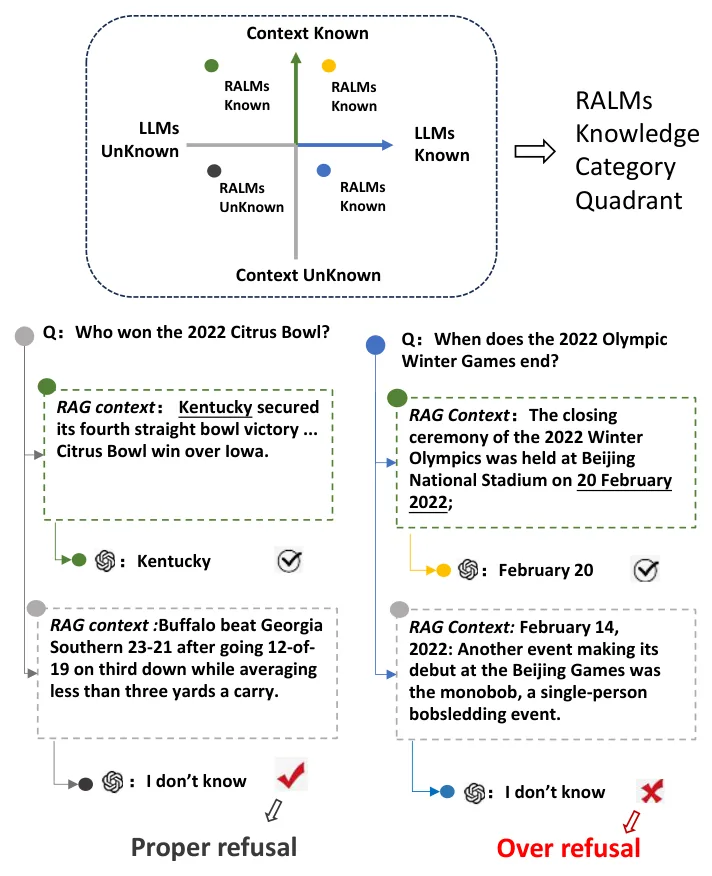
Do Retrieval Augmented Language Models Know When They Don’t Know?
AAAI 2026
Investigates refusal and uncertainty in retrieval-augmented language models, documenting over-refusal and studying methods that balance correct answers with appropriate abstention.
@inproceedings{ralm2026,
  title = {Do Retrieval Augmented Language Models Know When They Don’t Know?},
  author = {Zhou, Youchao and Huang, Heyan and Liu, Yicheng and Dai, Rui and Wang, Xinglin and Zhang, Xingchen and Shi, Shumin and Deng, Yang},
  year = {2026},
  url = {https://ojs.aaai.org/index.php/AAAI/article/view/40822},
  booktitle = {AAAI 2026},
  doi = {10.1609/aaai.v40i41.40822}
}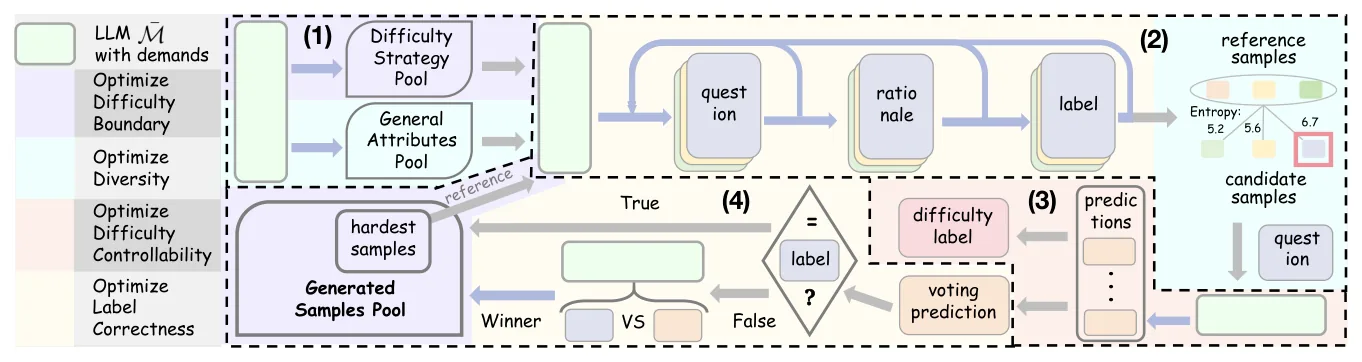
LLM-Powered Benchmark Factory: Reliable, Generic, and Efficient
ACL 2026
An automated framework for generating and validating task benchmarks, designed to make language-model evaluation more reliable and affordable.
@inproceedings{benchmaker2026,
  title = {LLM-Powered Benchmark Factory: Reliable, Generic, and Efficient},
  author = {Yuan, Peiwen and Feng, Shaoxiong and Li, Yiwei and Wang, Xinglin and Zhang, Yueqi and Shi, Jiayi and Tan, Chuyi and Pan, Boyuan and Hu, Yao and Li, Kan},
  year = {2026},
  url = {https://aclanthology.org/2026.acl-long.1661/},
  booktitle = {ACL 2026},
  doi = {10.18653/v1/2026.acl-long.1661}
}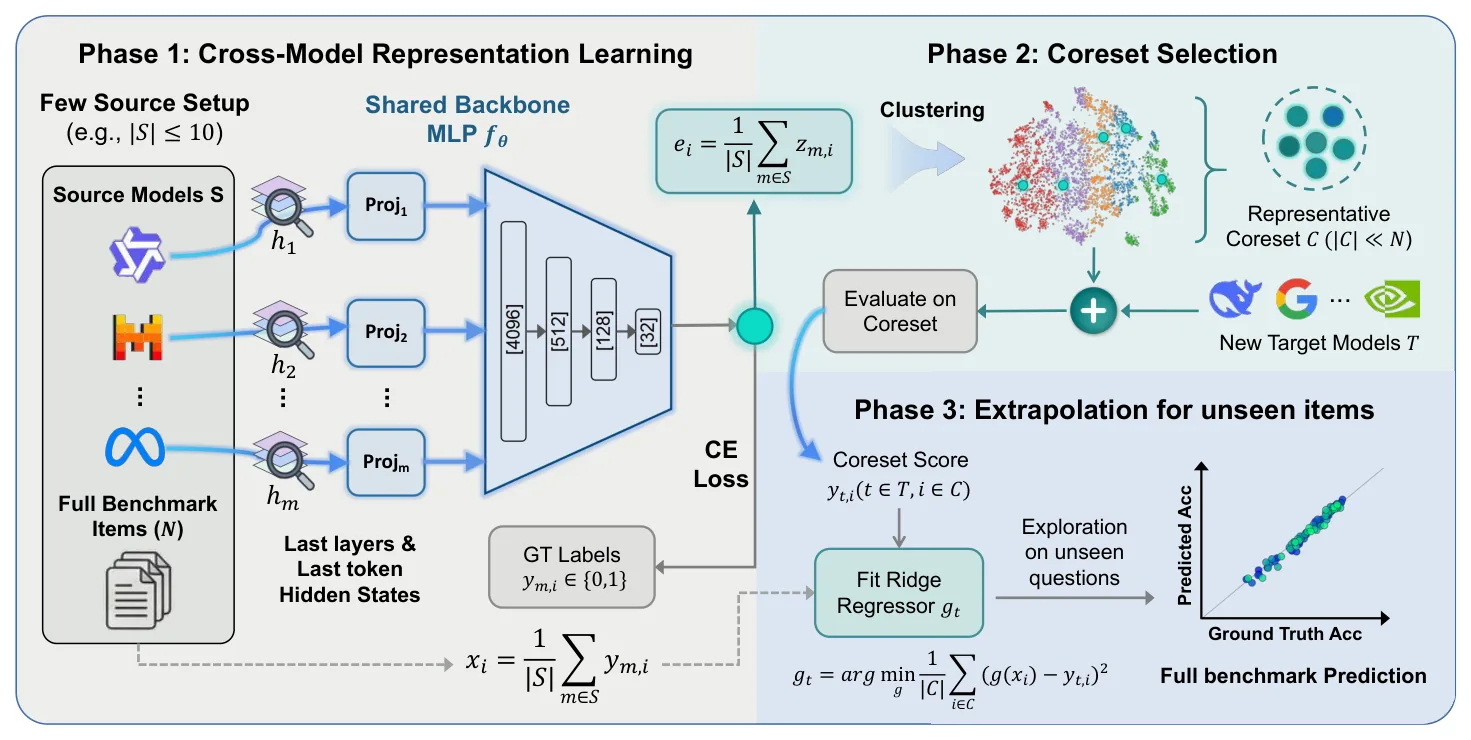
Learning More from Less: Unlocking Internal Representations for Benchmark Compression
ICML 2026
Aligns model hidden representations to select compact benchmark subsets, improving performance estimation when only a small pool of previously evaluated models is available.
@misc{repcore2026,
  title = {Learning More from Less: Unlocking Internal Representations for Benchmark Compression},
  author = {Zhang, Yueqi and Hu, Jin and Feng, Shaoxiong and Yuan, Peiwen and Wang, Xinglin and Li, Yiwei and Shi, Jiayi and Tan, Chuyi and Zhang, Ji and Pan, Boyuan and Hu, Yao and Li, Kan},
  year = {2026},
  url = {https://arxiv.org/abs/2602.00710},
  eprint = {2602.00710},
  archivePrefix = {arXiv},
  note = {Accepted to ICML 2026}
}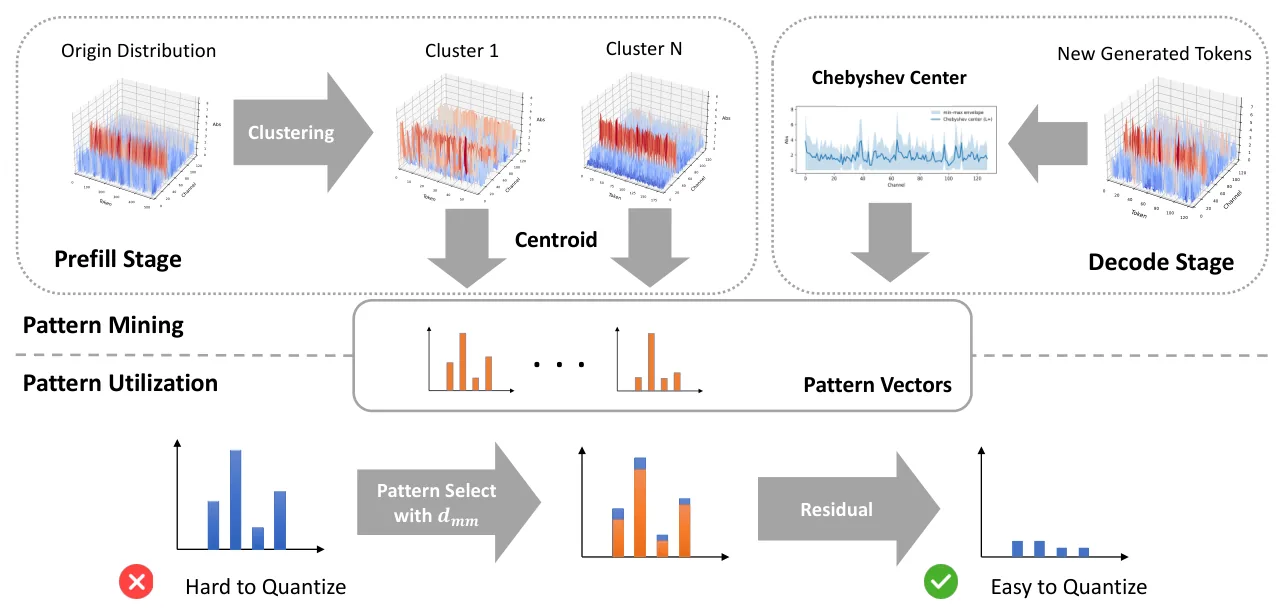
PatternKV: Flattening KV Representation Expands Quantization Headroom
ICML 2026
Finds recurring patterns in the key–value cache and quantizes residuals relative to those patterns, improving low-bit inference while reducing memory demands.
@misc{patternkv2025,
  title = {PatternKV: Flattening KV Representation Expands Quantization Headroom},
  author = {Zhang, Ji and Li, Yiwei and Feng, Shaoxiong and Yuan, Peiwen and Wang, Xinglin and Shi, Jiayi and Zhang, Yueqi and Tan, Chuyi and Pan, Boyuan and Hu, Yao and Li, Kan},
  year = {2025},
  url = {https://arxiv.org/abs/2510.05176},
  eprint = {2510.05176},
  archivePrefix = {arXiv},
  note = {Accepted to ICML 2026}
}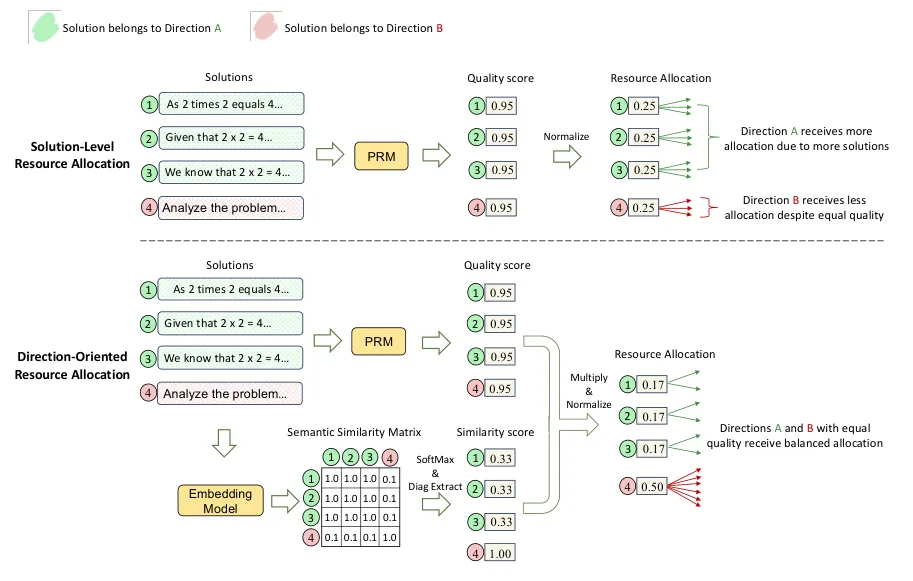
Every Rollout Counts: Optimal Resource Allocation for Efficient Test-Time Scaling
NeurIPS 2025
Treats test-time search as a resource-allocation problem and distributes rollouts across reasoning directions to improve the chance of finding a correct solution.
@inproceedings{dora2025,
  title = {Every Rollout Counts: Optimal Resource Allocation for Efficient Test-Time Scaling},
  author = {Wang, Xinglin and Li, Yiwei and Feng, Shaoxiong and Yuan, Peiwen and Zhang, Yueqi and Shi, Jiayi and Tan, Chuyi and Pan, Boyuan and Hu, Yao and Li, Kan},
  year = {2025},
  url = {https://papers.nips.cc/paper_files/paper/2025/hash/940b66bcdb34fb9ae47d85de838c372d-Abstract-Conference.html},
  booktitle = {NeurIPS 2025},
  doi = {10.52202/085713-3422}
}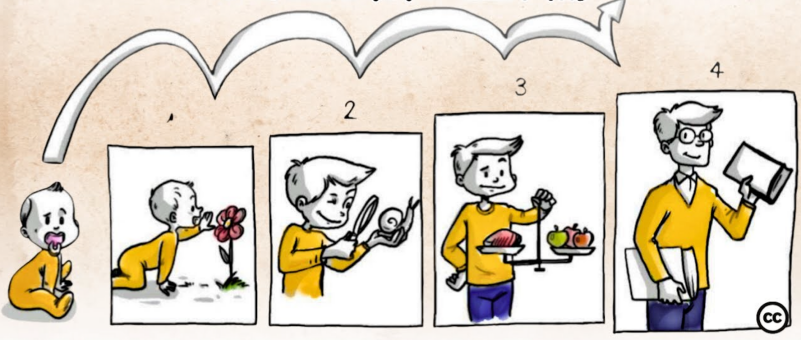
CogLM: Tracking Cognitive Development of Large Language Models
NAACL 2025 Oral
Introduces a benchmark grounded in cognitive-development theory to study language-model cognitive abilities and their relationships with model scale, training, and downstream performance.
@inproceedings{coglm2025,
  title = {CogLM: Tracking Cognitive Development of Large Language Models},
  author = {Wang, Xinglin and Yuan, Peiwen and Feng, Shaoxiong and Li, Yiwei and Pan, Boyuan and Wang, Heda and Hu, Yao and Li, Kan},
  year = {2025},
  url = {https://aclanthology.org/2025.naacl-long.4/},
  booktitle = {NAACL 2025},
  doi = {10.18653/v1/2025.naacl-long.4}
}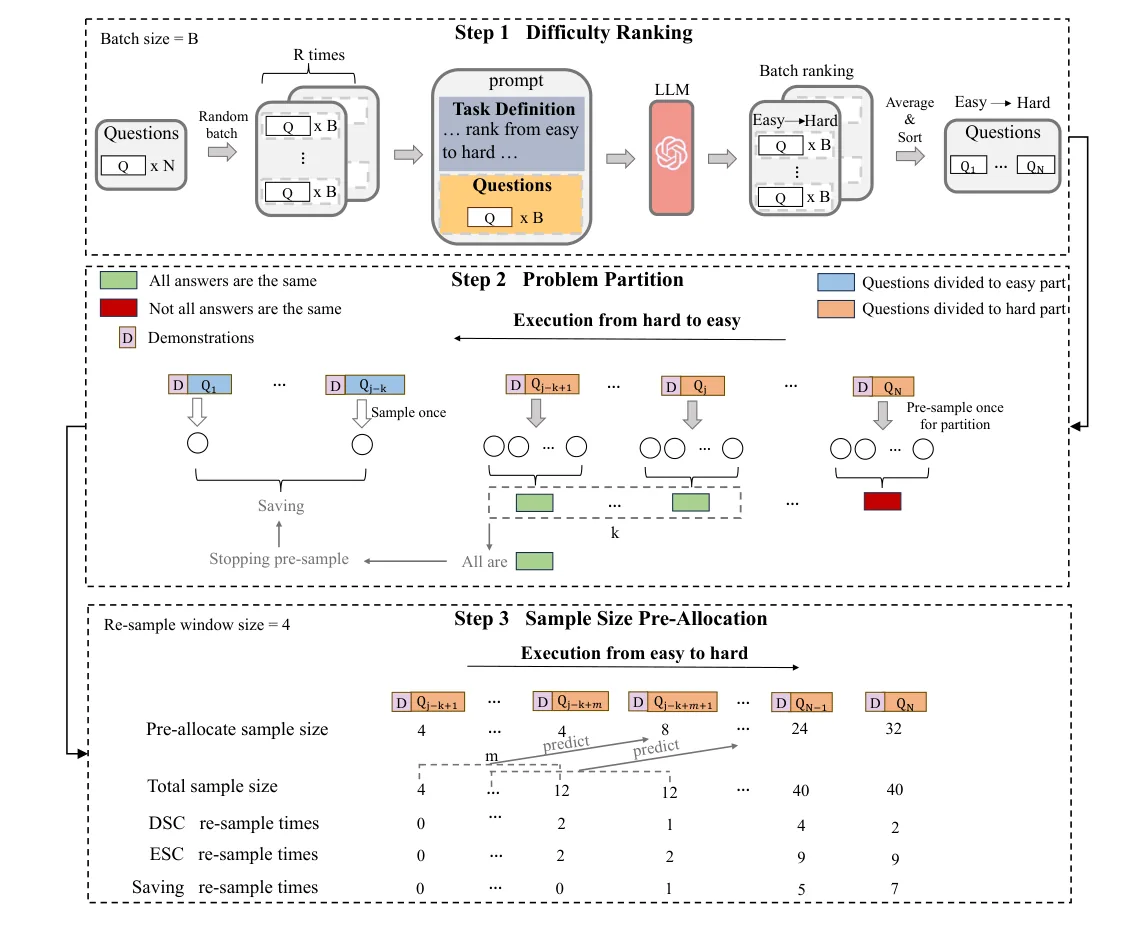
Make Every Penny Count: Difficulty-Adaptive Self-Consistency for Cost-Efficient Reasoning
Findings of NAACL 2025
Allocates self-consistency samples according to question difficulty and observed answer agreement, reducing reasoning cost across batches of questions.
@inproceedings{dsc2025,
  title = {Make Every Penny Count: Difficulty-Adaptive Self-Consistency for Cost-Efficient Reasoning},
  author = {Wang, Xinglin and Feng, Shaoxiong and Li, Yiwei and Yuan, Peiwen and Zhang, Yueqi and Tan, Chuyi and Pan, Boyuan and Hu, Yao and Li, Kan},
  year = {2025},
  url = {https://aclanthology.org/2025.findings-naacl.383/},
  booktitle = {Findings of NAACL 2025},
  doi = {10.18653/v1/2025.findings-naacl.383}
}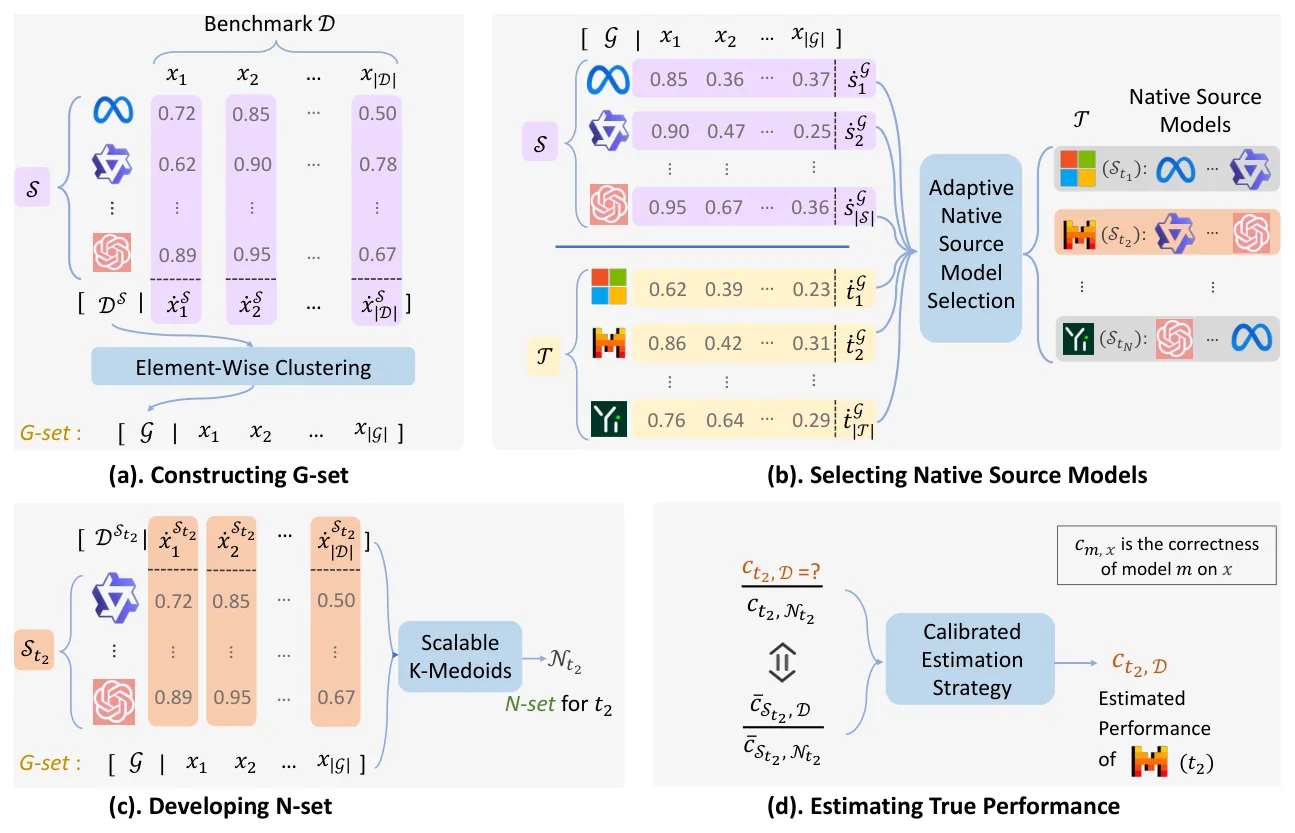
Beyond One-Size-Fits-All: Tailored Benchmarks for Efficient Evaluation
ACL 2025
Builds a benchmark subset tailored to each target model, using a shared probe and model-specific clustering to estimate full-benchmark performance efficiently.
@inproceedings{tailoredbench2025,
  title = {Beyond One-Size-Fits-All: Tailored Benchmarks for Efficient Evaluation},
  author = {Yuan, Peiwen and Zhang, Yueqi and Feng, Shaoxiong and Li, Yiwei and Wang, Xinglin and Shi, Jiayi and Tan, Chuyi and Pan, Boyuan and Hu, Yao and Li, Kan},
  year = {2025},
  url = {https://aclanthology.org/2025.acl-long.759/},
  booktitle = {ACL 2025},
  doi = {10.18653/v1/2025.acl-long.759}
}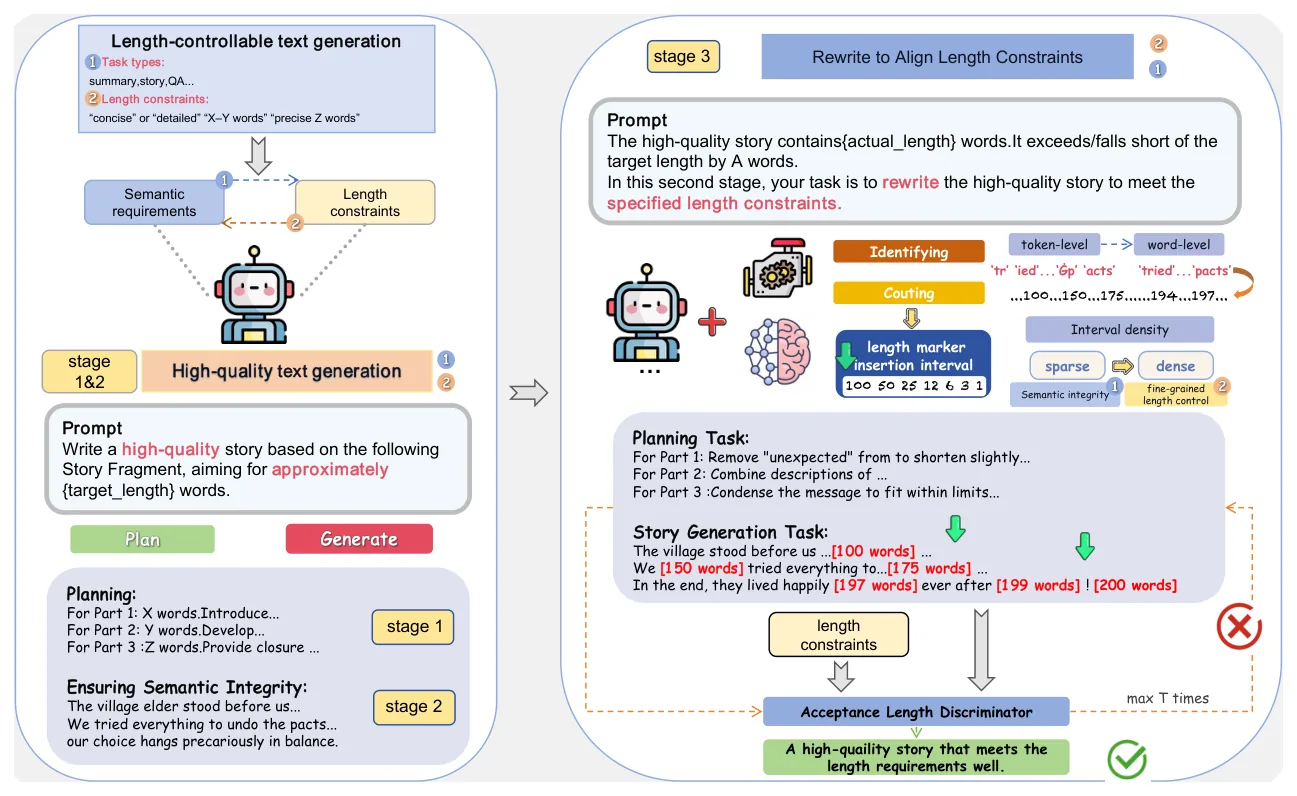
From Sub-Ability Diagnosis to Human-Aligned Generation: Bridging the Gap for Text Length Control via MarkerGen
ACL 2025
Diagnoses the component skills needed for length-controlled writing and uses external tools, inserted markers, and staged generation to improve length adherence.
@inproceedings{markergen2025,
  title = {From Sub-Ability Diagnosis to Human-Aligned Generation: Bridging the Gap for Text Length Control via MarkerGen},
  author = {Yuan, Peiwen and Tan, Chuyi and Feng, Shaoxiong and Li, Yiwei and Wang, Xinglin and Zhang, Yueqi and Shi, Jiayi and Pan, Boyuan and Hu, Yao and Li, Kan},
  year = {2025},
  url = {https://aclanthology.org/2025.acl-long.850/},
  booktitle = {ACL 2025},
  doi = {10.18653/v1/2025.acl-long.850}
}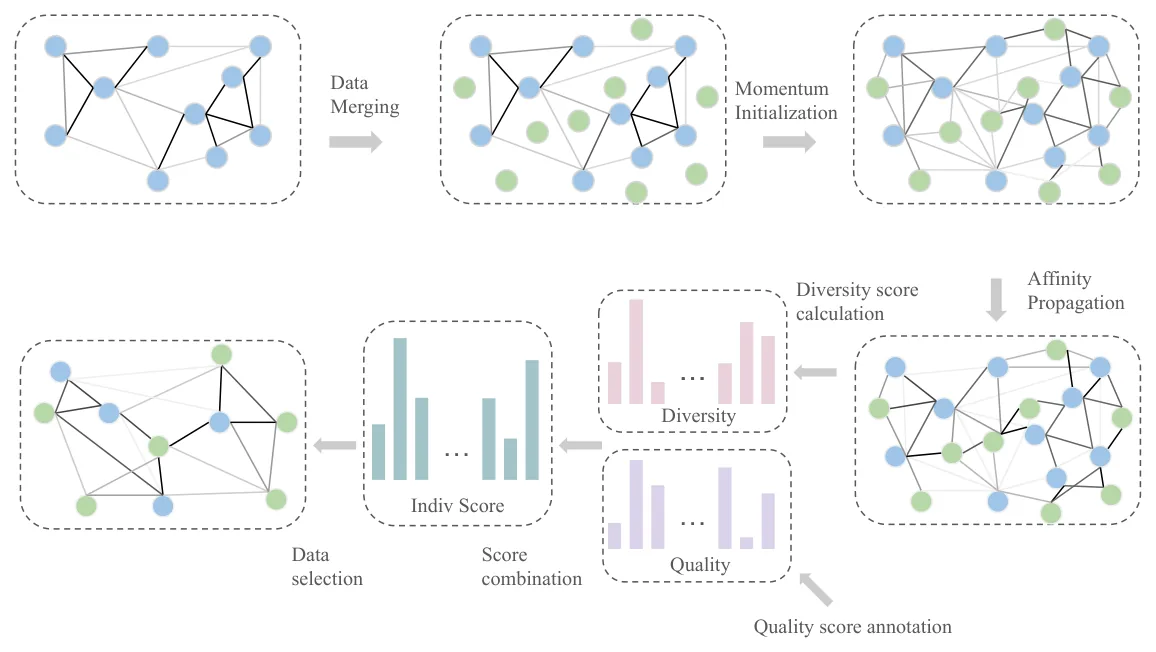
InsBank: Evolving Instruction Subset for Ongoing Alignment
Findings of EMNLP 2025
Maintains an evolving bank of diverse, high-quality instruction examples, enabling instruction-tuning subsets to improve as new data becomes available.
@inproceedings{insbank2025,
  title = {InsBank: Evolving Instruction Subset for Ongoing Alignment},
  author = {Shi, Jiayi and Li, Yiwei and Feng, Shaoxiong and Yuan, Peiwen and Wang, Xinglin and Zhang, Yueqi and Tan, Chuyi and Pan, Boyuan and Ren, Huan and Hu, Yao and Li, Kan},
  year = {2025},
  url = {https://aclanthology.org/2025.findings-emnlp.14/},
  booktitle = {Findings of EMNLP 2025},
  doi = {10.18653/v1/2025.findings-emnlp.14}
}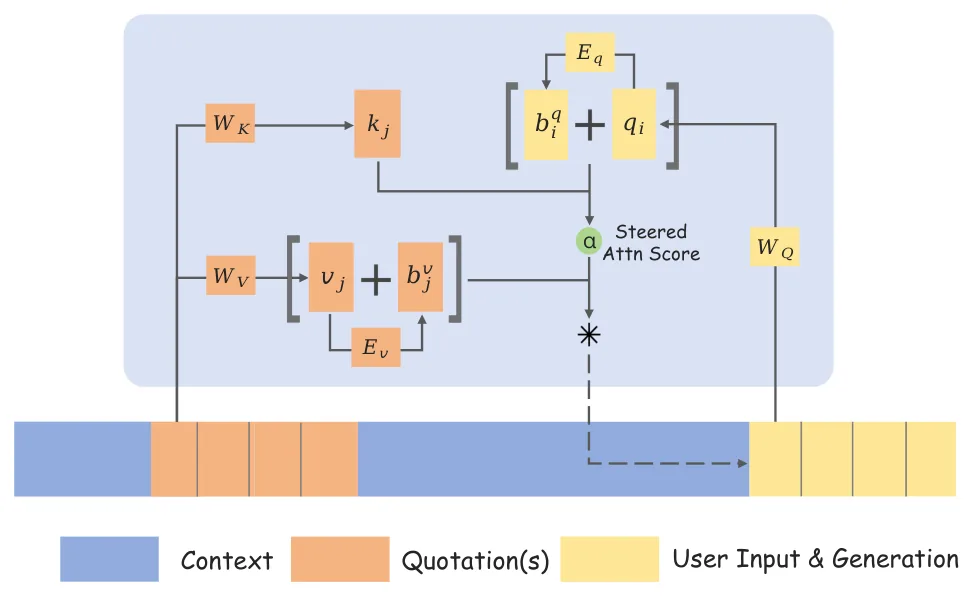
Mind the Quote: Enabling Quotation-Aware Dialogue in LLMs via Plug-and-Play Modules
NeurIPS 2025
Introduces quotation-aware dialogue tasks and compact attention adapters that help models use explicitly selected spans from conversation history.
@inproceedings{quada2025,
  title = {Mind the Quote: Enabling Quotation-Aware Dialogue in LLMs via Plug-and-Play Modules},
  author = {Zhang, Yueqi and Yuan, Peiwen and Li, Yiwei and Feng, Shaoxiong and Wang, Xinglin and Shi, Jiayi and Tan, Chuyi and Pan, Boyuan and Hu, Yao and Li, Kan},
  year = {2025},
  url = {https://papers.nips.cc/paper_files/paper/2025/hash/938ac7bb9a997b60b6be0348c486aaef-Abstract-Conference.html},
  booktitle = {NeurIPS 2025},
  doi = {10.52202/085713-3411}
}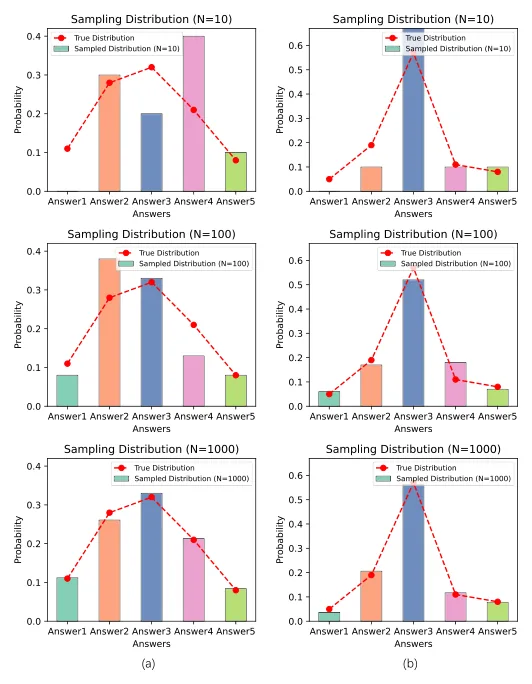
Revisiting Self-Consistency from Dynamic Distributional Alignment Perspective on Answer Aggregation
Findings of ACL 2025
Analyzes self-consistency as distributional alignment and adapts sampling temperature using confidence to balance exploration with reliable answer aggregation.
@inproceedings{dda2025,
  title = {Revisiting Self-Consistency from Dynamic Distributional Alignment Perspective on Answer Aggregation},
  author = {Li, Yiwei and Zhang, Ji and Feng, Shaoxiong and Yuan, Peiwen and Wang, Xinglin and Shi, Jiayi and Zhang, Yueqi and Tan, Chuyi and Pan, Boyuan and Hu, Yao and Li, Kan},
  year = {2025},
  url = {https://aclanthology.org/2025.findings-acl.1293/},
  booktitle = {Findings of ACL 2025},
  doi = {10.18653/v1/2025.findings-acl.1293}
}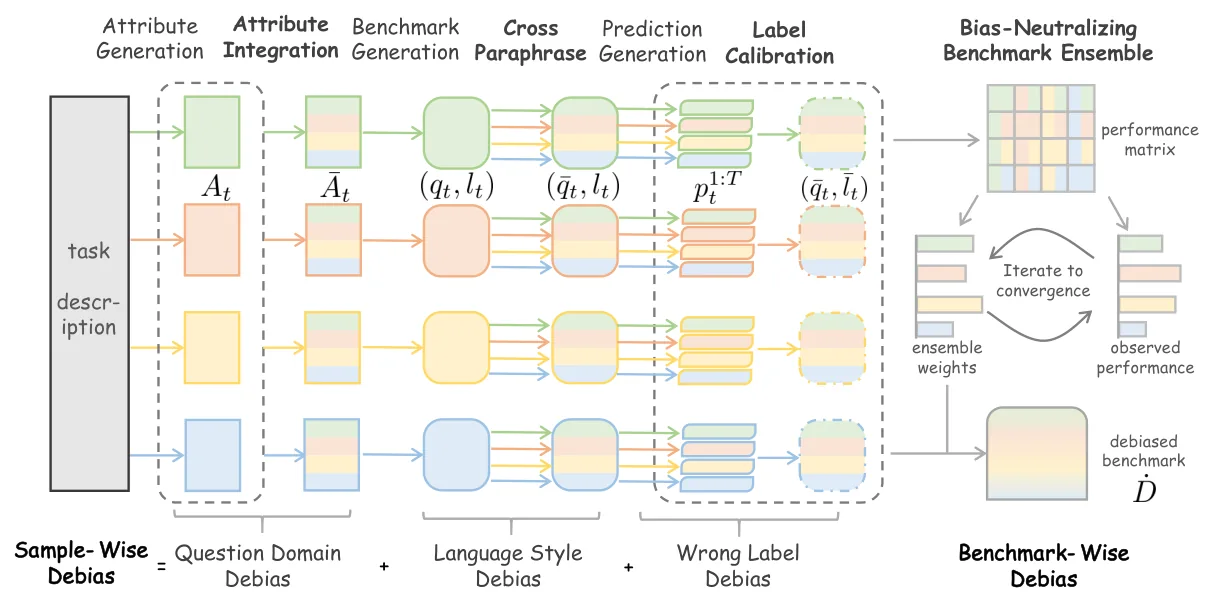
Silencer: From Discovery to Mitigation of Self-Bias in LLM-as-Benchmark-Generator
NeurIPS 2025
Studies the advantage models can receive on their own generated benchmarks and combines heterogeneous generators to reduce this evaluation bias.
@inproceedings{silencer2025,
  title = {Silencer: From Discovery to Mitigation of Self-Bias in LLM-as-Benchmark-Generator},
  author = {Yuan, Peiwen and Li, Yiwei and Feng, Shaoxiong and Wang, Xinglin and Zhang, Yueqi and Shi, Jiayi and Tan, Chuyi and Pan, Boyuan and Hu, Yao and Li, Kan},
  year = {2025},
  url = {https://papers.nips.cc/paper_files/paper/2025/hash/bc24200f4ed9a5bbf821c0ad18e605da-Abstract-Conference.html},
  booktitle = {NeurIPS 2025},
  doi = {10.52202/085713-4317}
}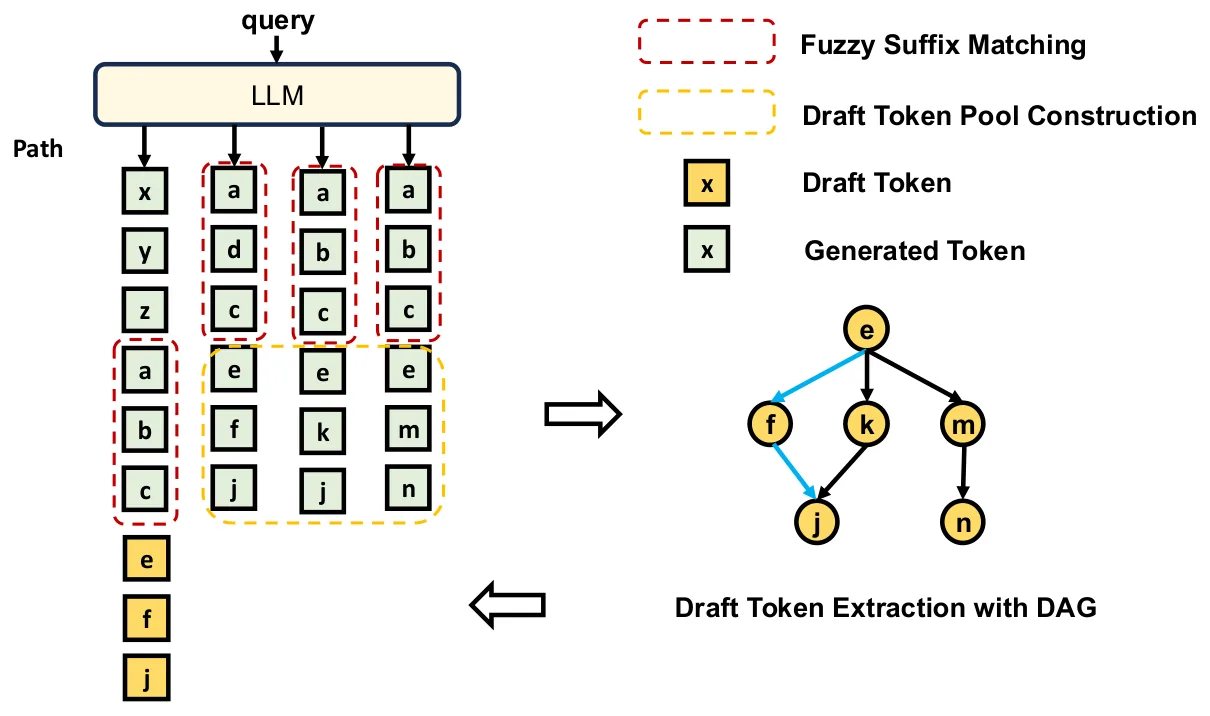
Speculative Decoding for Multi-Sample Inference
Findings of EMNLP 2025
Uses agreement across parallel reasoning paths to construct speculative draft tokens, accelerating multi-sample inference without an auxiliary draft model.
@inproceedings{sdms2025,
  title = {Speculative Decoding for Multi-Sample Inference},
  author = {Li, Yiwei and Shi, Jiayi and Feng, Shaoxiong and Yuan, Peiwen and Wang, Xinglin and Zhang, Yueqi and Zhang, Ji and Tan, Chuyi and Pan, Boyuan and Hu, Yao and Li, Kan},
  year = {2025},
  url = {https://aclanthology.org/2025.findings-emnlp.668/},
  booktitle = {Findings of EMNLP 2025},
  doi = {10.18653/v1/2025.findings-emnlp.668}
}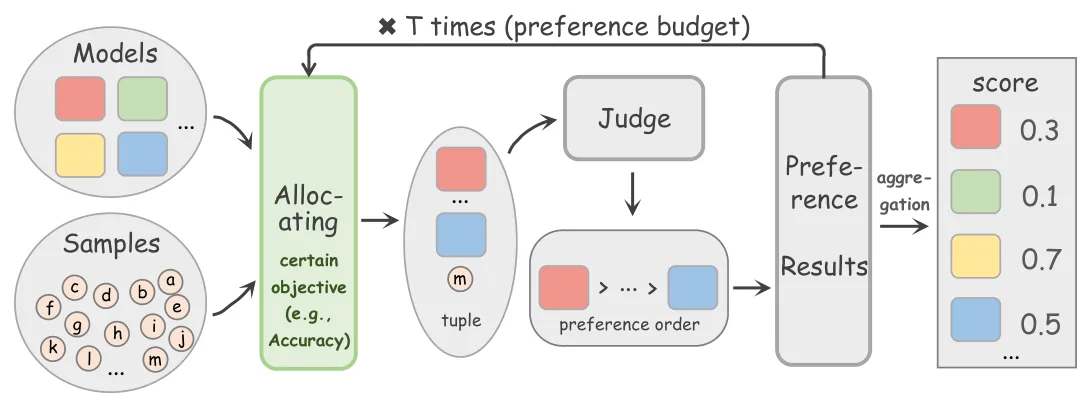
UniCBE: An Uniformity-driven Comparing Based Evaluation Framework with Unified Multi-Objective Optimization
ICLR 2025 · Spotlight
Coordinates preference comparisons through a uniformity-driven sampling framework that improves evaluation accuracy, convergence, and scalability as new models arrive.
@inproceedings{unicbe2025,
  title = {UniCBE: An Uniformity-driven Comparing Based Evaluation Framework with Unified Multi-Objective Optimization},
  author = {Yuan, Peiwen and Feng, Shaoxiong and Li, Yiwei and Wang, Xinglin and Zhang, Yueqi and Shi, Jiayi and Tan, Chuyi and Pan, Boyuan and Hu, Yao and Li, Kan},
  year = {2025},
  url = {https://openreview.net/forum?id=rpwGUtTeA5},
  booktitle = {ICLR 2025}
}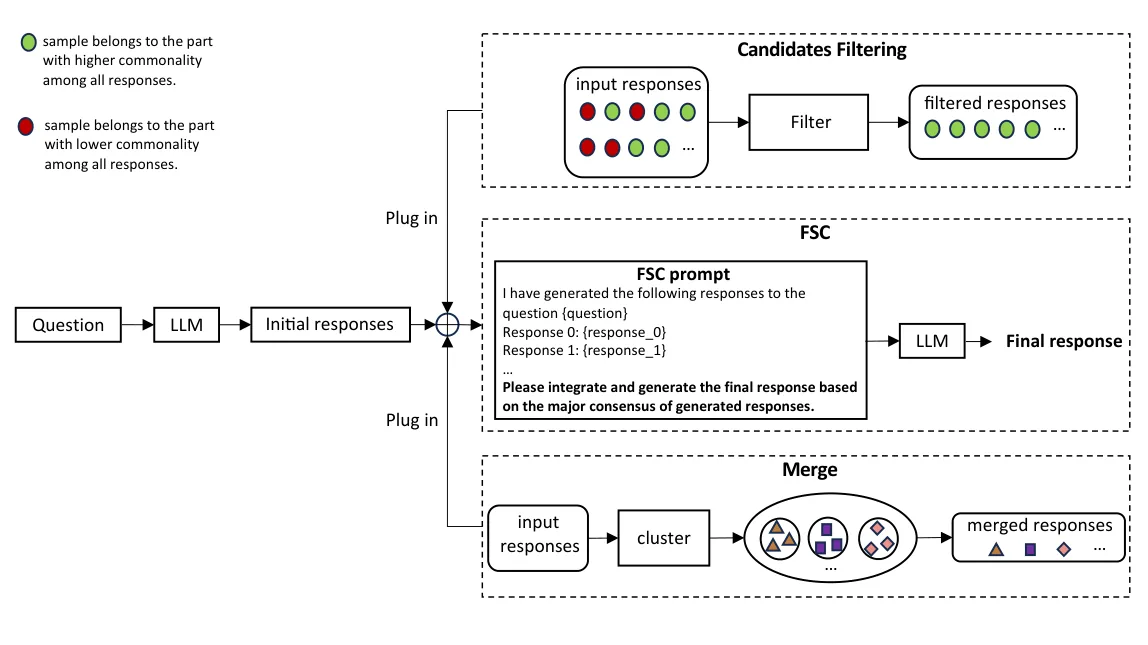
Integrate the Essence and Eliminate the Dross: Fine-Grained Self-Consistency for Free-Form Language Generation
ACL 2024 Main
Extracts and combines shared information across generated candidates at the segment level, extending self-consistency to free-form generation.
@inproceedings{fsc2024,
  title = {Integrate the Essence and Eliminate the Dross: Fine-Grained Self-Consistency for Free-Form Language Generation},
  author = {Wang, Xinglin and Li, Yiwei and Feng, Shaoxiong and Yuan, Peiwen and Pan, Boyuan and Wang, Heda and Hu, Yao and Li, Kan},
  year = {2024},
  url = {https://aclanthology.org/2024.acl-long.634/},
  booktitle = {ACL 2024},
  doi = {10.18653/v1/2024.acl-long.634}
}
Generative Dense Retrieval: Memory Can Be a Burden
EACL 2024 Oral
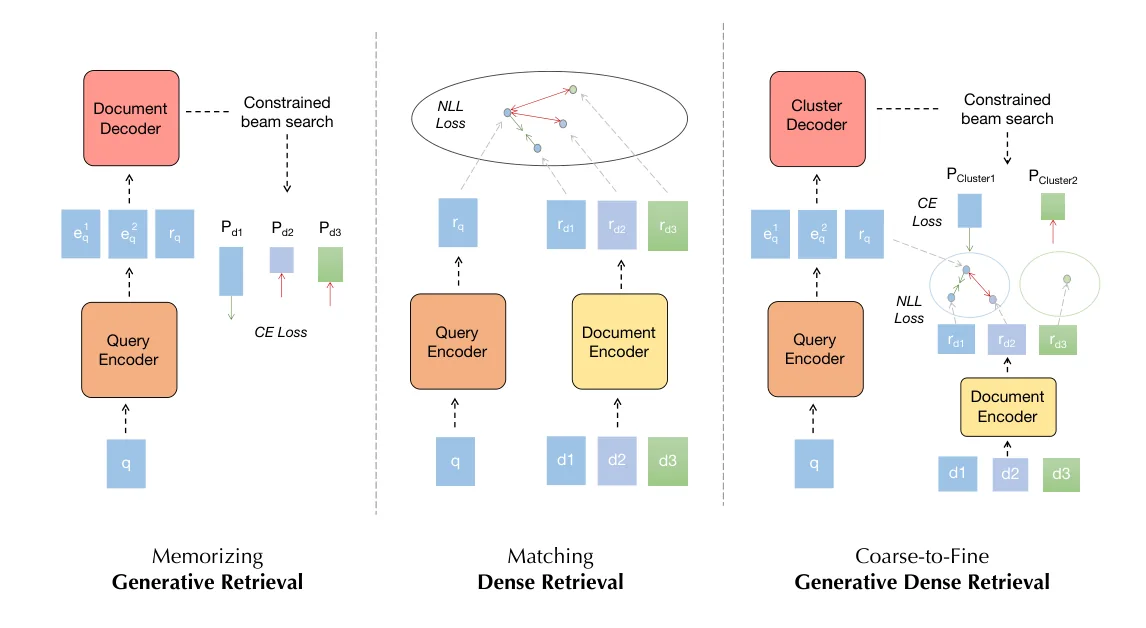
Combines generative retrieval of document clusters with dense retrieval within each cluster, addressing the scalability and update costs of memorizing entire corpora.
@inproceedings{gdr2024,
  title = {Generative Dense Retrieval: Memory Can Be a Burden},
  author = {Yuan, Peiwen and Wang, Xinglin and Feng, Shaoxiong and Pan, Boyuan and Li, Yiwei and Wang, Heda and Miao, Xupeng and Li, Kan},
  year = {2024},
  url = {https://aclanthology.org/2024.eacl-long.173/},
  booktitle = {EACL 2024},
  doi = {10.18653/v1/2024.eacl-long.173}
}
BatchEval: Towards Human-like Text Evaluation
ACL 2024 Oral
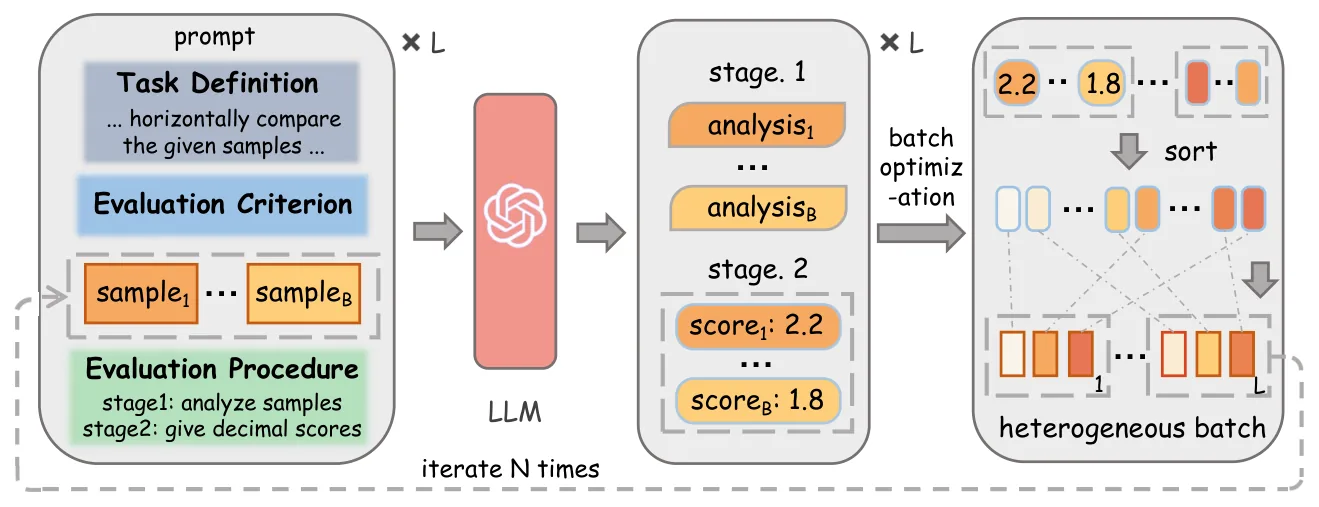
Evaluates text in batches with iterative comparisons, improving robustness and agreement with human judgments while reducing evaluation cost.
@inproceedings{batcheval2024,
  title = {BatchEval: Towards Human-like Text Evaluation},
  author = {Yuan, Peiwen and Feng, Shaoxiong and Li, Yiwei and Wang, Xinglin and Pan, Boyuan and Wang, Heda and Hu, Yao and Li, Kan},
  year = {2024},
  url = {https://aclanthology.org/2024.acl-long.846/},
  booktitle = {ACL 2024},
  doi = {10.18653/v1/2024.acl-long.846}
}
Escape Sky-high Cost: Early-stopping Self-Consistency for Multi-step Reasoning
ICLR 2024
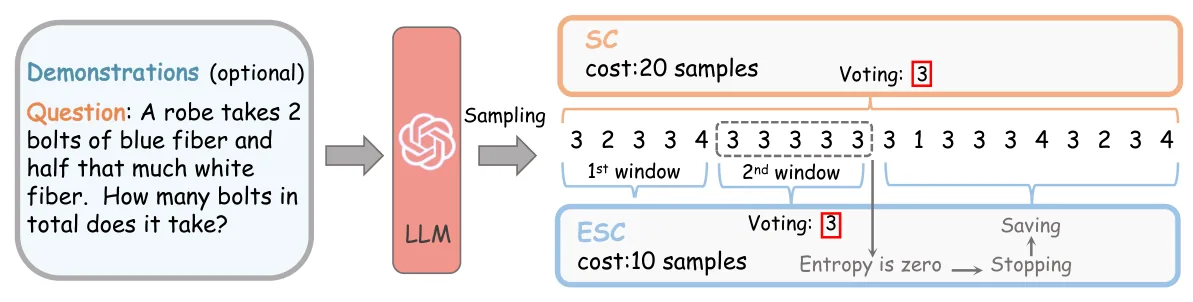
Stops self-consistency sampling once sufficient agreement emerges, reducing the inference cost of reasoning while retaining answer quality.
@inproceedings{esc2024,
  title = {Escape Sky-high Cost: Early-stopping Self-Consistency for Multi-step Reasoning},
  author = {Li, Yiwei and Yuan, Peiwen and Feng, Shaoxiong and Pan, Boyuan and Wang, Xinglin and Sun, Bin and Wang, Heda and Li, Kan},
  year = {2024},
  url = {https://arxiv.org/abs/2401.10480},
  booktitle = {ICLR 2024}
}
Focused Large Language Models are Stable Many-Shot Learners
EMNLP 2024
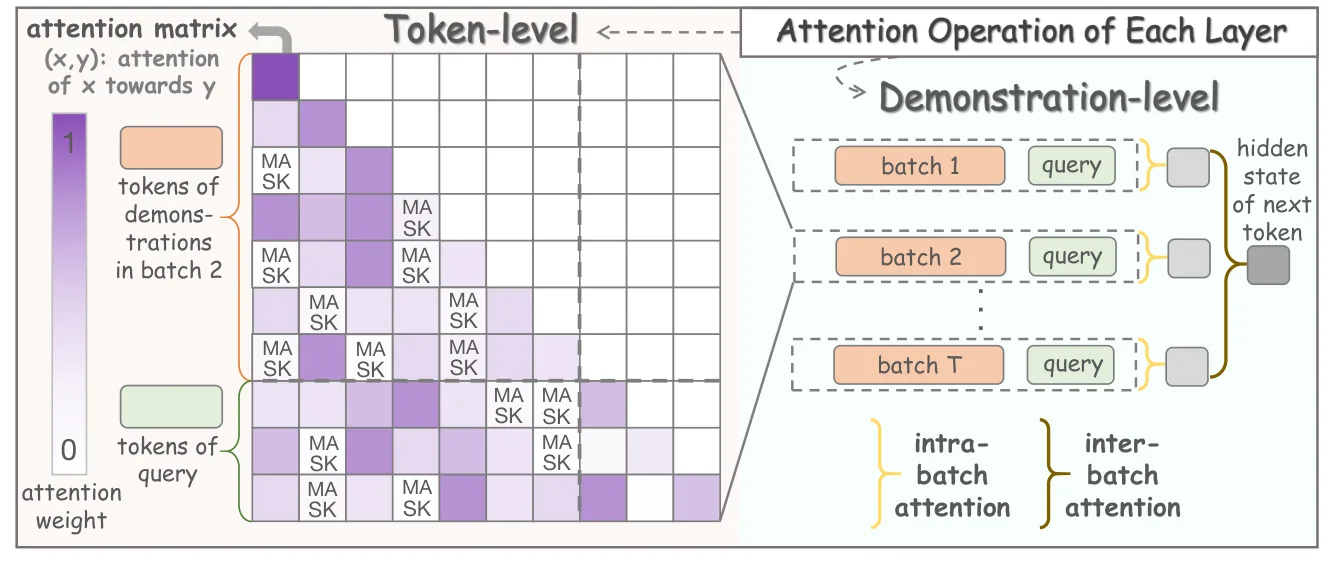
Improves many-shot in-context learning by filtering low-value content and organizing attention so that long demonstrations preserve focus on the current query.
@inproceedings{focusicl2024,
  title = {Focused Large Language Models are Stable Many-Shot Learners},
  author = {Yuan, Peiwen and Feng, Shaoxiong and Li, Yiwei and Wang, Xinglin and Zhang, Yueqi and Tan, Chuyi and Pan, Boyuan and Wang, Heda and Hu, Yao and Li, Kan},
  year = {2024},
  url = {https://aclanthology.org/2024.emnlp-main.359/},
  booktitle = {EMNLP 2024},
  doi = {10.18653/v1/2024.emnlp-main.359}
}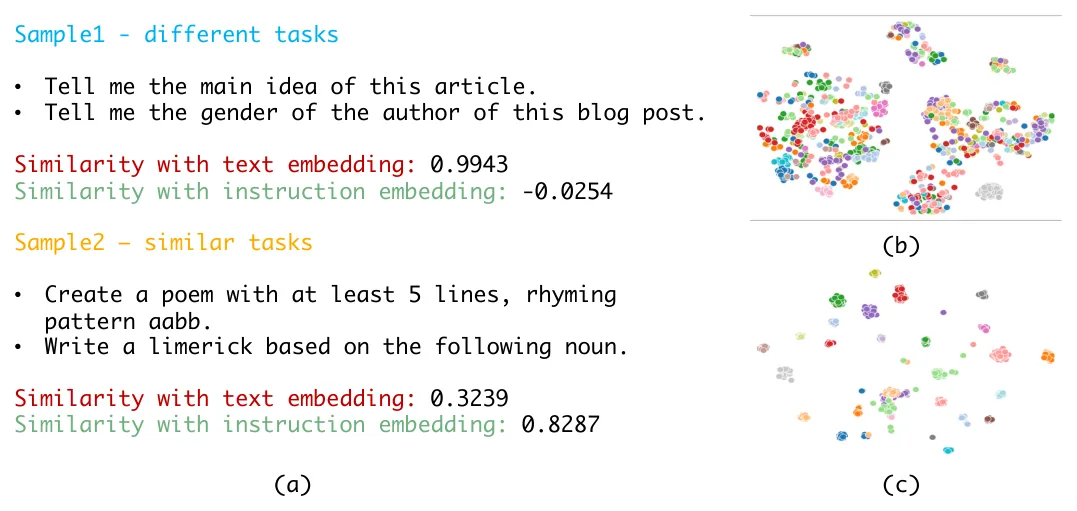
Instruction Embedding: Latent Representations of Instructions Towards Task Identification
NeurIPS 2024 · Datasets and Benchmarks
Introduces instruction embeddings and a benchmark for representing the task requested by an instruction, supporting task identification and instruction-data selection.
@inproceedings{ieb2024,
  title = {Instruction Embedding: Latent Representations of Instructions Towards Task Identification},
  author = {Li, Yiwei and Shi, Jiayi and Feng, Shaoxiong and Yuan, Peiwen and Wang, Xinglin and Pan, Boyuan and Wang, Heda and Hu, Yao and Li, Kan},
  year = {2024},
  url = {https://papers.nips.cc/paper_files/paper/2024/hash/9f9e2982759f384495f4b75a33f3dd72-Abstract-Datasets_and_Benchmarks_Track.html},
  booktitle = {NeurIPS 2024},
  doi = {10.52202/079017-2784}
}
Poor-Supervised Evaluation for SuperLLM via Mutual Consistency
Findings of ACL 2024
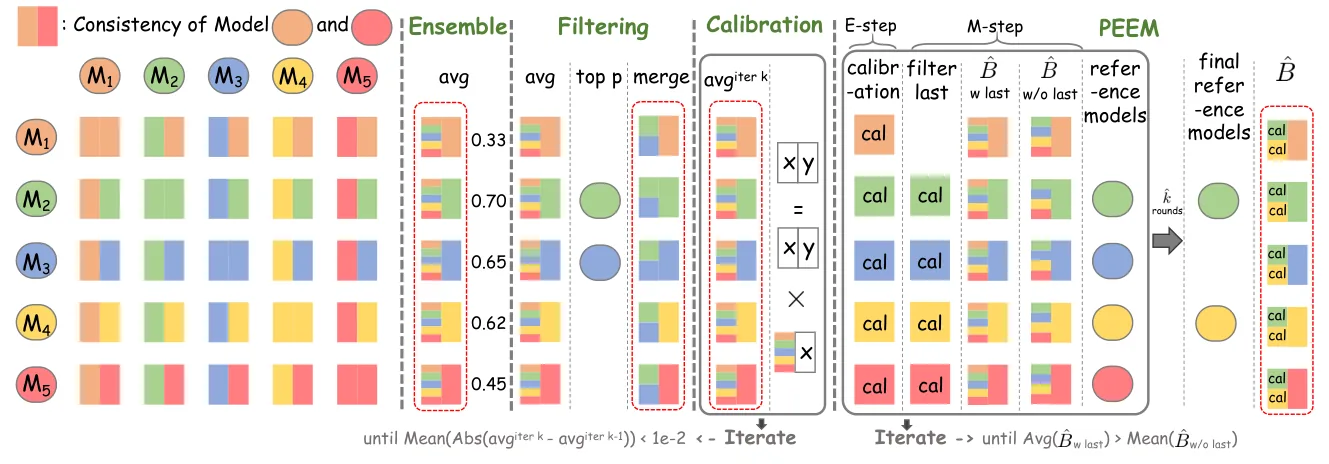
Evaluates language models without reliable gold labels by estimating their capabilities from mutual prediction consistency and iteratively weighting reference models.
@inproceedings{peem2024,
  title = {Poor-Supervised Evaluation for SuperLLM via Mutual Consistency},
  author = {Yuan, Peiwen and Feng, Shaoxiong and Li, Yiwei and Wang, Xinglin and Pan, Boyuan and Wang, Heda and Hu, Yao and Li, Kan},
  year = {2024},
  url = {https://aclanthology.org/2024.findings-acl.690/},
  booktitle = {Findings of ACL 2024},
  doi = {10.18653/v1/2024.findings-acl.690}
}
Subtopic-aware View Sampling and Temporal Aggregation for Long-form Document Matching
arXiv preprint
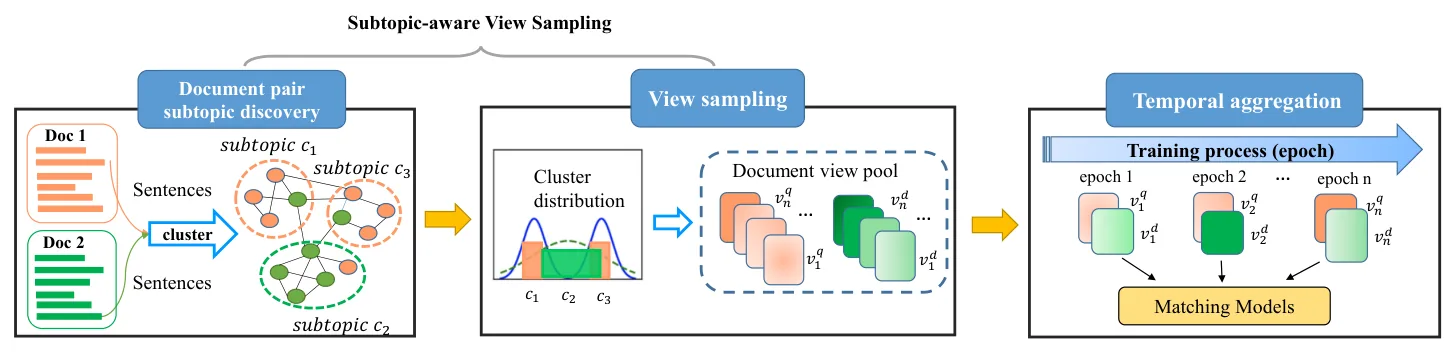
Samples document views around multiple subtopics and aggregates their matching signals over training, improving the representation of heterogeneous evidence in long documents.
@misc{sst2024,
  title = {Subtopic-aware View Sampling and Temporal Aggregation for Long-form Document Matching},
  author = {Zhou, Youchao and Huang, Heyan and Wu, Zhijing and Liu, Yuhang and Wang, Xinglin},
  year = {2024},
  url = {https://arxiv.org/abs/2412.07573},
  eprint = {2412.07573},
  archivePrefix = {arXiv}
}
Turning Dust into Gold: Distilling Complex Reasoning Capabilities from LLMs by Leveraging Negative Data
AAAI 2024 Oral
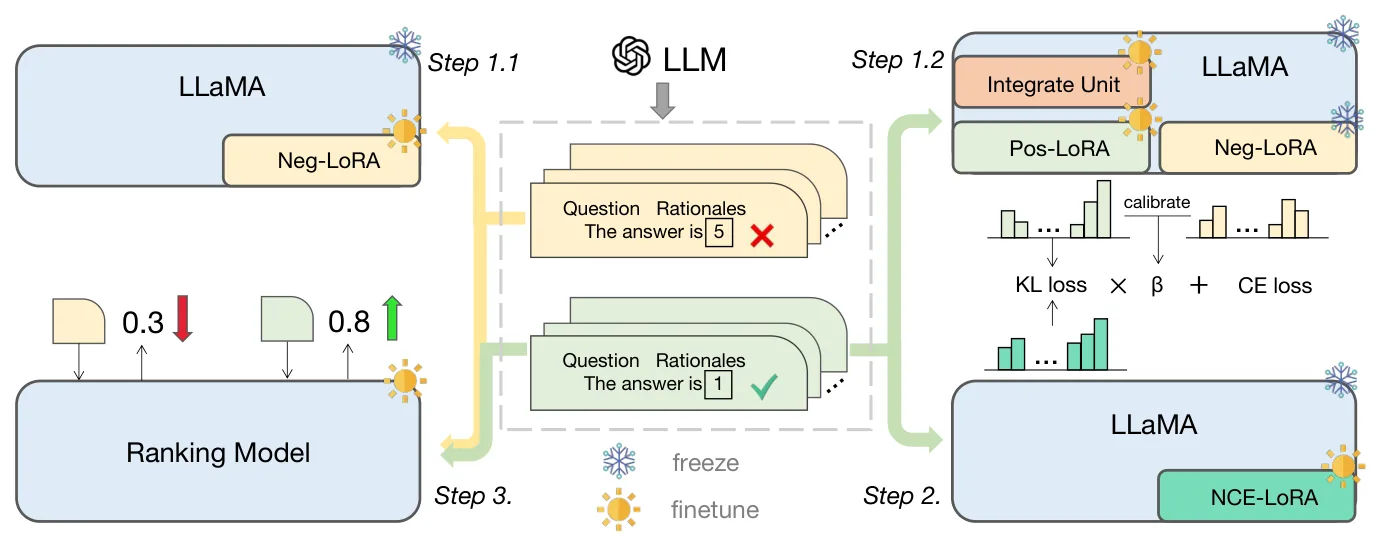
Uses both correct and incorrect reasoning examples to transfer complex reasoning skills from large language models into smaller models.
@inproceedings{tdg2024,
  title = {Turning Dust into Gold: Distilling Complex Reasoning Capabilities from LLMs by Leveraging Negative Data},
  author = {Li, Yiwei and Yuan, Peiwen and Feng, Shaoxiong and Pan, Boyuan and Sun, Bin and Wang, Xinglin and Wang, Heda and Li, Kan},
  year = {2024},
  url = {https://ojs.aaai.org/index.php/AAAI/article/view/29821},
  booktitle = {AAAI 2024},
  doi = {10.1609/aaai.v38i17.29821}
}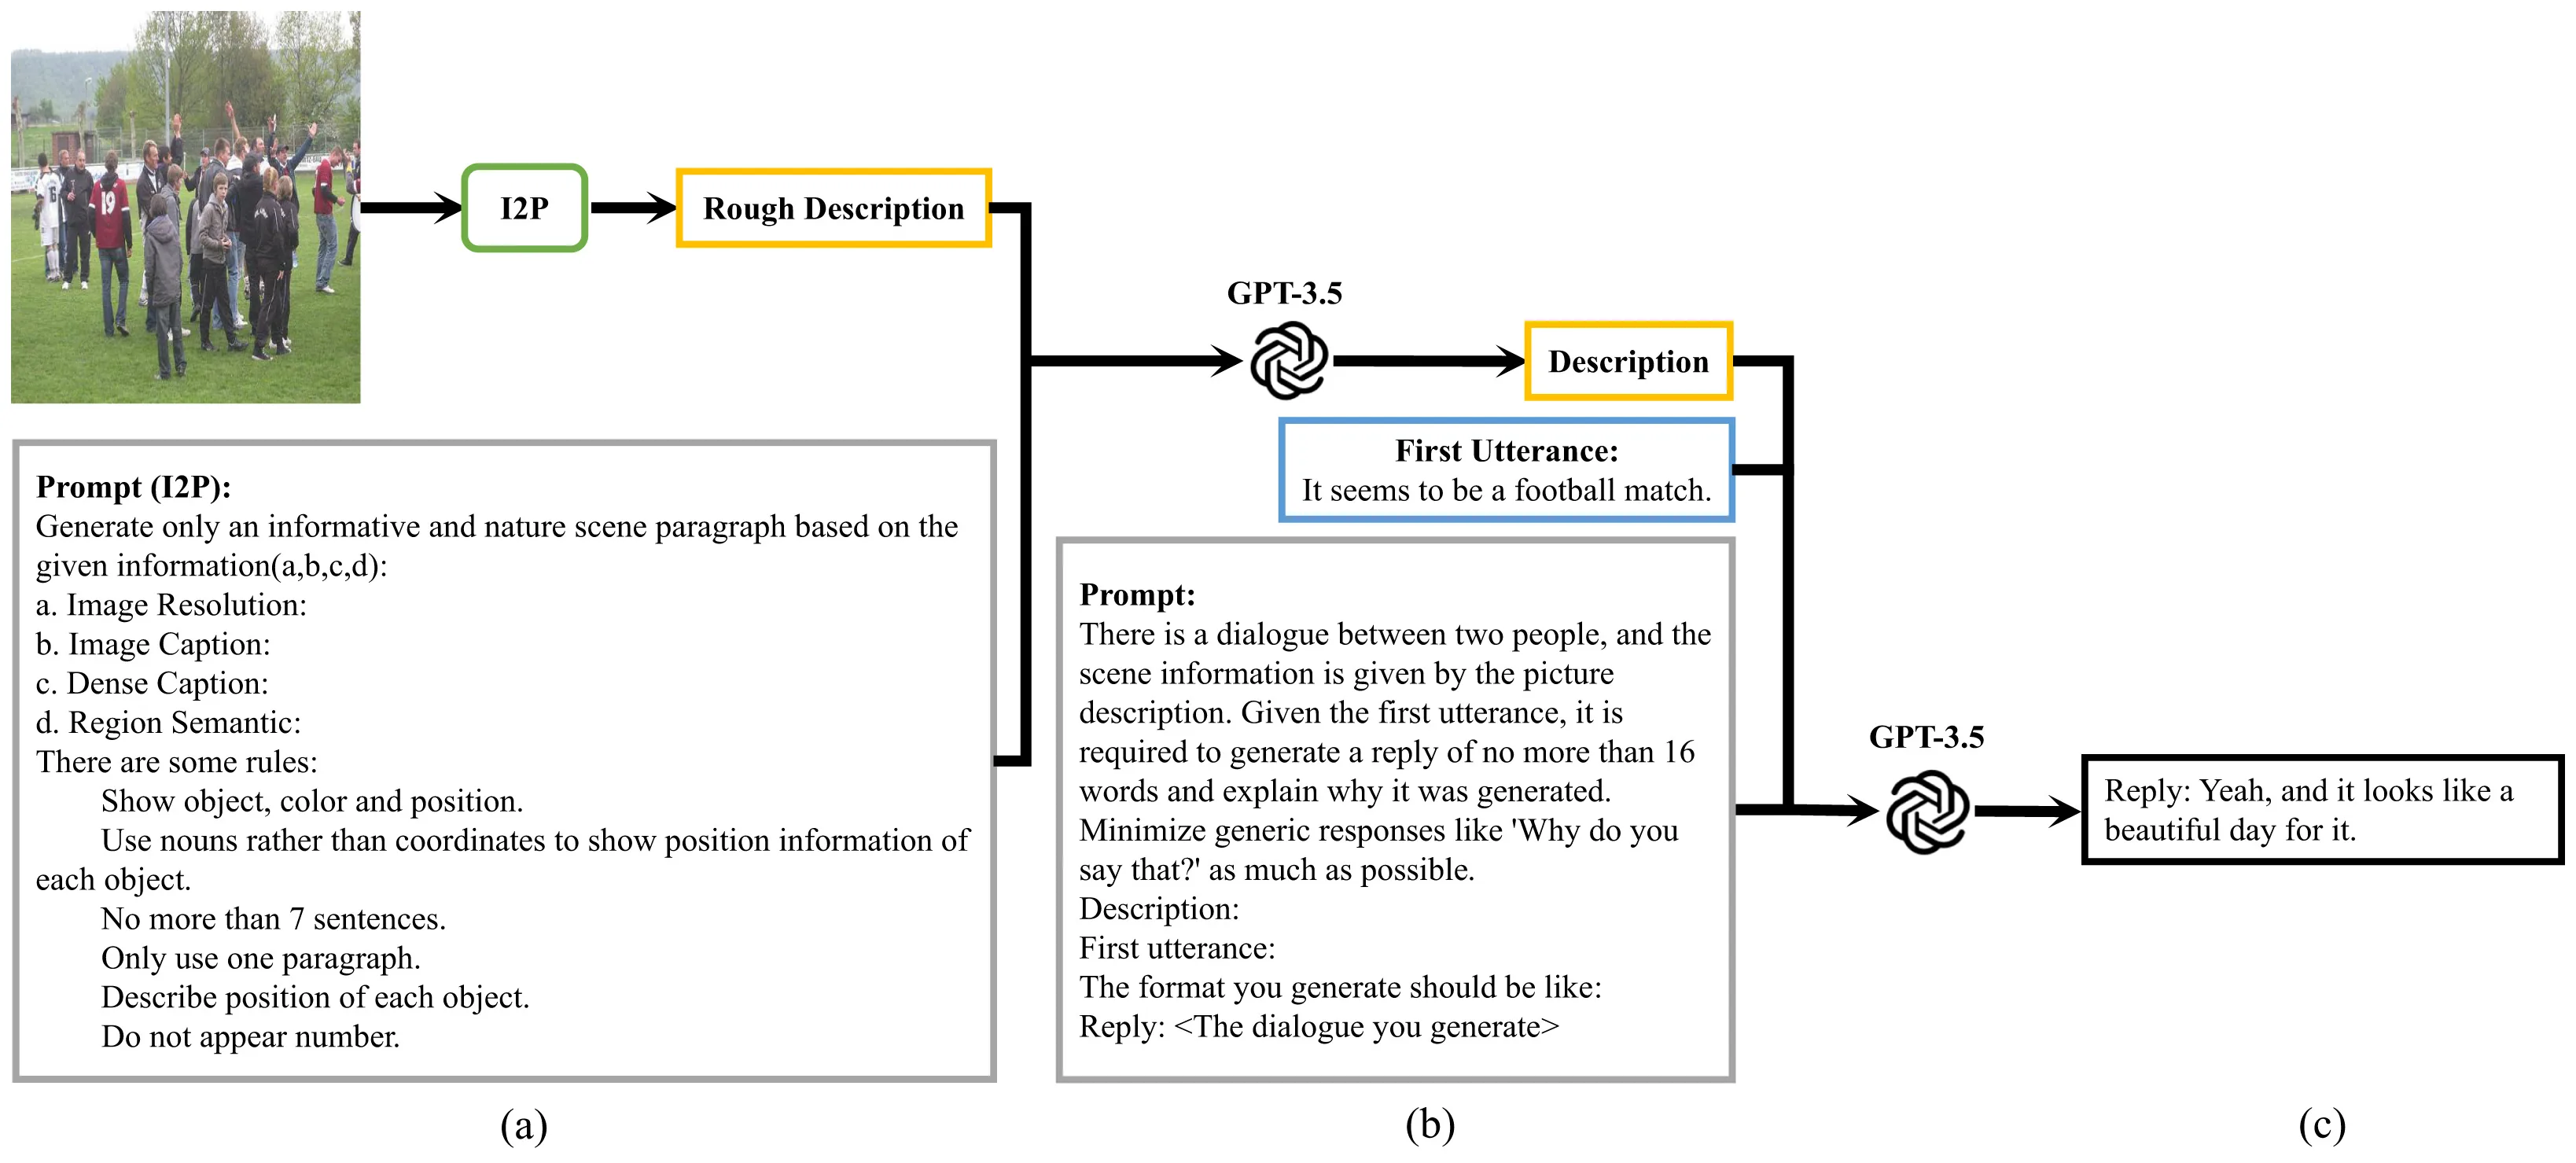
MODE+: A benchmark and a probe into multimodal open-domain dialogue evaluation
Neurocomputing 675, 132787
Provides a human-annotated benchmark for evaluating multimodal dialogue and studies an evaluation framework combining image transformation, reasoning, and calibration.
@article{mode2026,
  title = {MODE+: A benchmark and a probe into multimodal open-domain dialogue evaluation},
  author = {Yin, Hang and Wang, Xinglin and Zhang, Yueqi and Lu, Pinren and Sun, Bin and Yuan, Peiwen and Li, Kan},
  year = {2026},
  url = {https://www.sciencedirect.com/science/article/pii/S0925231226001840},
  journal = {Neurocomputing 675, 132787},
  doi = {10.1016/j.neucom.2026.132787}
}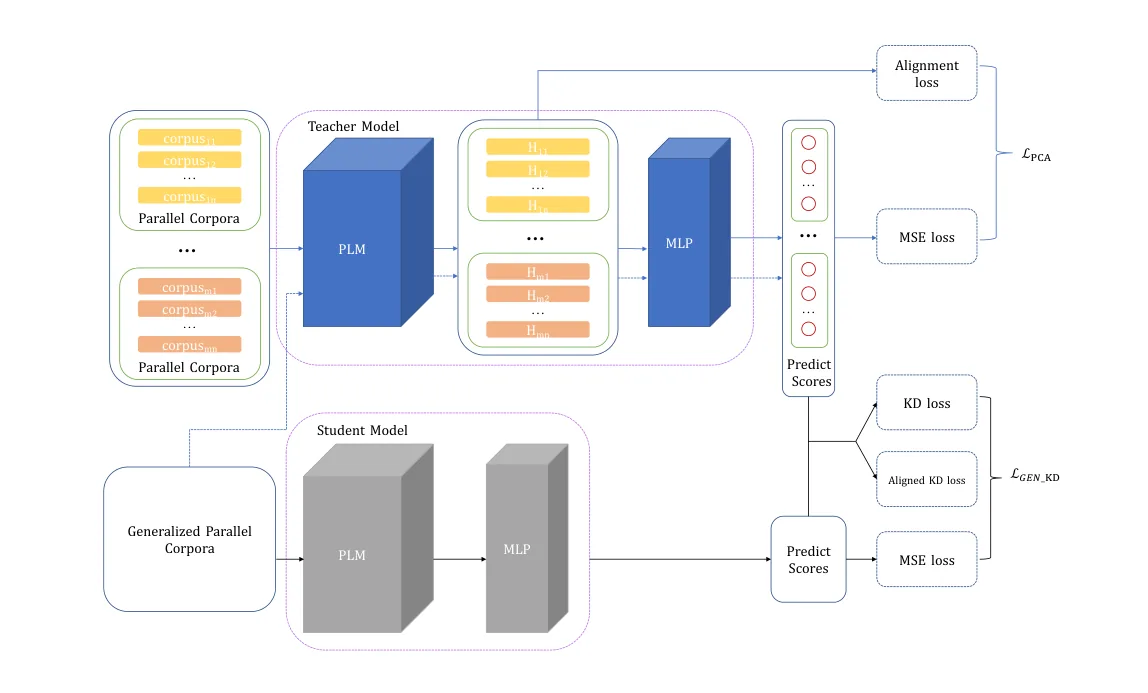
Parallel Corpora Alignment Framework for Multilingual and Robust Automatic Dialogue Evaluation
DSTC11 Workshop 2023
Aligns semantically equivalent dialogue corpora through contrastive learning and distillation, improving evaluation consistency across languages and domains.
@inproceedings{pcaf2023,
  title = {Parallel Corpora Alignment Framework for Multilingual and Robust Automatic Dialogue Evaluation},
  author = {Wang, Xinglin and Shi, Jiayi and Yuan, Peiwen and Li, Kan},
  year = {2023},
  url = {https://aclanthology.org/2023.dstc-1.15/},
  booktitle = {DSTC11 Workshop 2023},
  doi = {10.18653/v1/2023.dstc-1.15}
}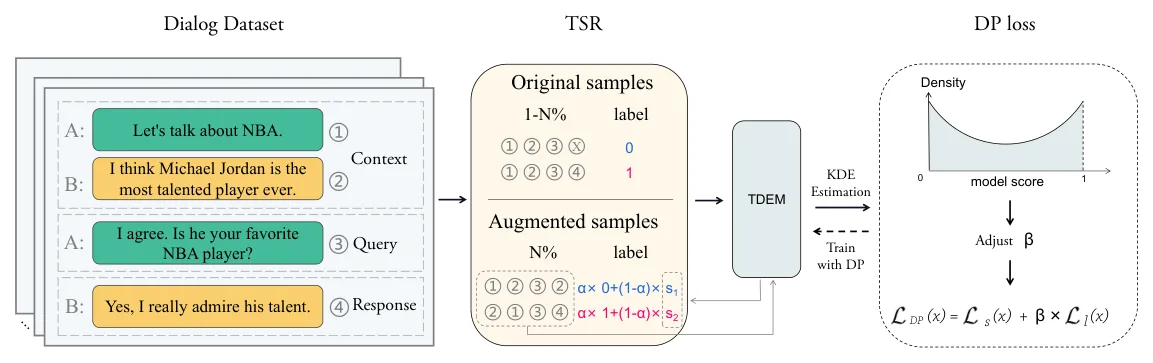
Better Correlation and Robustness: A Distribution-Balanced Self-Supervised Learning Framework for Automatic Dialogue Evaluation
NeurIPS 2023
Balances training coherence and output scores in self-supervised dialogue evaluation to improve agreement with human judgments and robustness.
@inproceedings{bcr2023,
  title = {Better Correlation and Robustness: A Distribution-Balanced Self-Supervised Learning Framework for Automatic Dialogue Evaluation},
  author = {Yuan, Peiwen and Wang, Xinglin and Shi, Jiayi and Sun, Bin and Li, Yiwei and Li, Kan},
  year = {2023},
  url = {https://papers.nips.cc/paper_files/paper/2023/hash/a8b148559549ce33261e79b4400e0d77-Abstract-Conference.html},
  booktitle = {NeurIPS 2023},
  doi = {10.52202/075280-2343}
}
See also Google Scholar for citations and updates.
MCPP accepted to NeurIPS 2026; CPT accepted to EMNLP 2026 as an Oral presentation.
Joined Alibaba Qwen as a research intern.
Completed my research internship at Xiaohongshu.
Joined Xiaohongshu as a research intern.